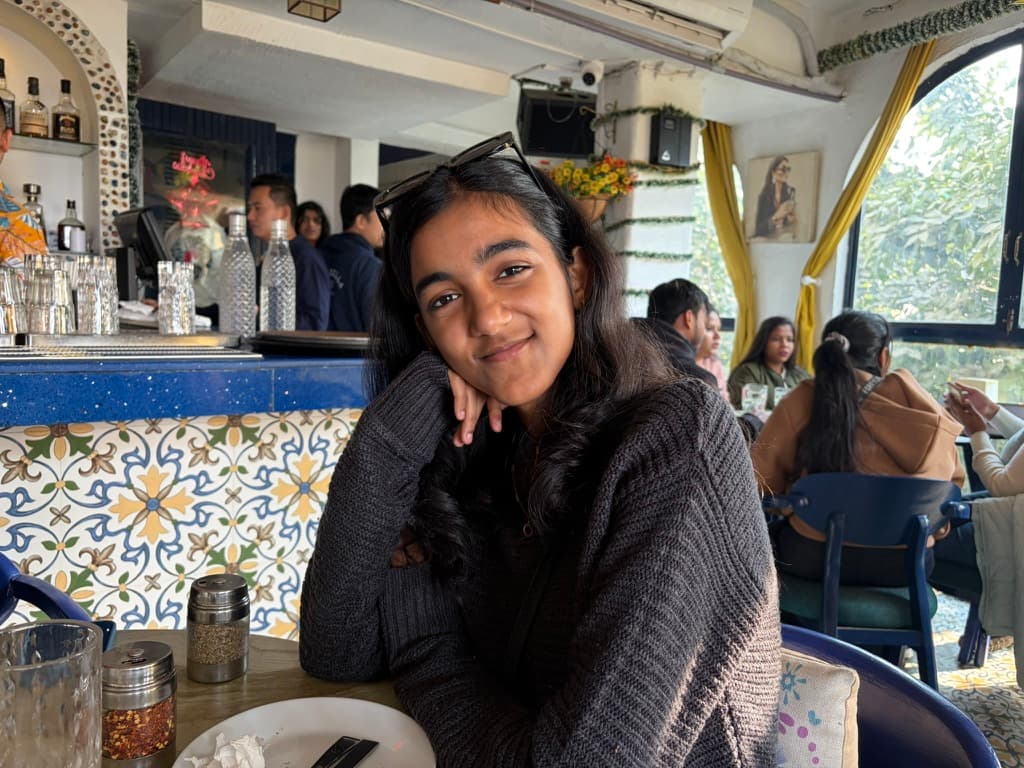
hello, नमस्ते, こんにちは
i'm ayushi yadav, a
cloud & devops engineer working on observability & automation.
i work across aws, terraform, and observability stacks, and build incident-response tooling like polaris and remediate. go and python. aws certified in cloudops and data engineering.
available for cloud/devops roles
ghaziabad, india, gmt+5:30
01: about
cloud & devops, end to end.
• i work across the stack: aws infrastructure, terraform, ci/cd, and prometheus/grafana observability.
• currently building incident-response platforms (polaris, remediate) that detect failures and trigger automated remediation.
• upstream open-source contributor, and b.tech it student at kiet ghaziabad (expected 2028, gpa 8.11).
02: skills
technical skills.
languages
cloud & infra
ci/cd & gitops
observability
web
03: experience
experience.
open source, cloud native
open-source contributor • jun 2026 to present
- • prometheus/alertmanager: extracted notifier validation into independent validate() methods across all 22 notifier types for cleaner error aggregation.
- • kgateway: fixed frontendtls cert validation bug for cross-namespace listenersets + strengthened regression tests for multi-tenant tls.
- • argoproj/argo-cd: resolved 12+ cves via go dependency upgrades, verified with go build + govulncheck, fixed ci in maintainer-reviewed prs.
x402-open
cloud deployment • oct 2025
- • provisioned and deployed full app stack on aws ec2 with public access on ubuntu linux.
- • configured networking, security groups, env vars, and git-based deploy workflows end-to-end.
kiet, department of it
kubernetes workshop instructor • 2026
- • designed and delivered a 3-hour kubernetes workshop: containers from first principles, docker hands-on, and live cluster demos.
- • built a 3-node proxmox lab with cloud-init ubuntu vms, then ran a k3s cluster on top for the live sessions.
- • ran live failure drills: pod deletion, node drains, and simulated node failure, with prometheus/grafana observability throughout.
04: projects
selected projects.
★ 2 • github.com/ayushi-work/polaris
polaris: k8s incident simulation & self-healing
injects controlled failures, correlates logs/metrics/traces, generates ai-assisted incident reports. automated restarts, rollbacks, scaling via go + k8s apis + prometheus + grafana + opentelemetry. may 2026.
github.com/ayushi-work/remediate
remediate: automated devops incident response
end-to-end pipeline: ingests logs + prometheus metrics, classifies via llm (langgraph + aws bedrock), triggers remediation playbooks. k8s + alerting rules + grafana + helm. nov 2025.
05: github & oss
open source contributions.
live contribution graph, click to open my profile
github.com/ayushi-work ↗06: process
how i work.
01 assess
understand the current state first: review dashboards, map dependencies, and define slos before making changes.
aws, diagrams, notion
02 automate
codify repeatable work. terraform for infrastructure, containers for workloads, gitops for deployments.
terraform, docker, actions
03 observe
instrument systems and alert on what matters: metrics, logs, and traces with actionable thresholds.
prometheus, grafana, opentelemetry
04 harden
address vulnerabilities, maintain backups, and monitor costs.
govulncheck, velero, budgets
07: notes
writing.
understanding bottlerocket from an sre perspective
immutable, container-optimized os vs amazon linux: patching, incident response, and observability trade-offs for eks fleets.
polaris: ai-powered kubernetes incident detection & self-healing
watches pods for oomkilled/crashloopbackoff, sends context to an llm for rca, executes remediation. go, client-go, chaos mode included.
zero-downtime kubernetes upgrades using a self-healing approach
cordon → drain → upgrade → verify, one node at a time. pdbs, rolling updates, readiness probes, and letting metrics gate the rollout.
build a three-tier web app on aws
cloudfront + s3 frontend, api gateway + lambda logic tier, dynamodb data tier: full step-by-step with code and screenshots.
using chaos engineering on aws to find real bottlenecks
nat gateways, retry storms, slow autoscaling, control-plane limits: what fis experiments reveal that staging never will.
console-only real-time data ingestion & storage pipeline on aws
real-time ingestion to storage built entirely from the aws console: no cli, no iac, pure click-path engineering.
decision support tool (built with kiro)
a decision-support app built with kiro, most-discussed post on the profile with 6 comments.
08: playground
design work.
09: watching
currently watching.
 netflix
house, m.d.
s3 e19 of 24
late into season 3. the differentials never get old.
 netflix
brooklyn nine-nine
s3 e2 of 23, fifth rewatch
fifth time through. still the best cold opens on television.
10: contact
get in touch.
i am currently open to cloud/devops roles and freelance infrastructure work. feel free to reach out. i typically respond within 24 hours.
ghaziabad, india • email is the fastest way to reach me